
Publication·
GrainSpeech preprint: compact speech synthesis with finer detail
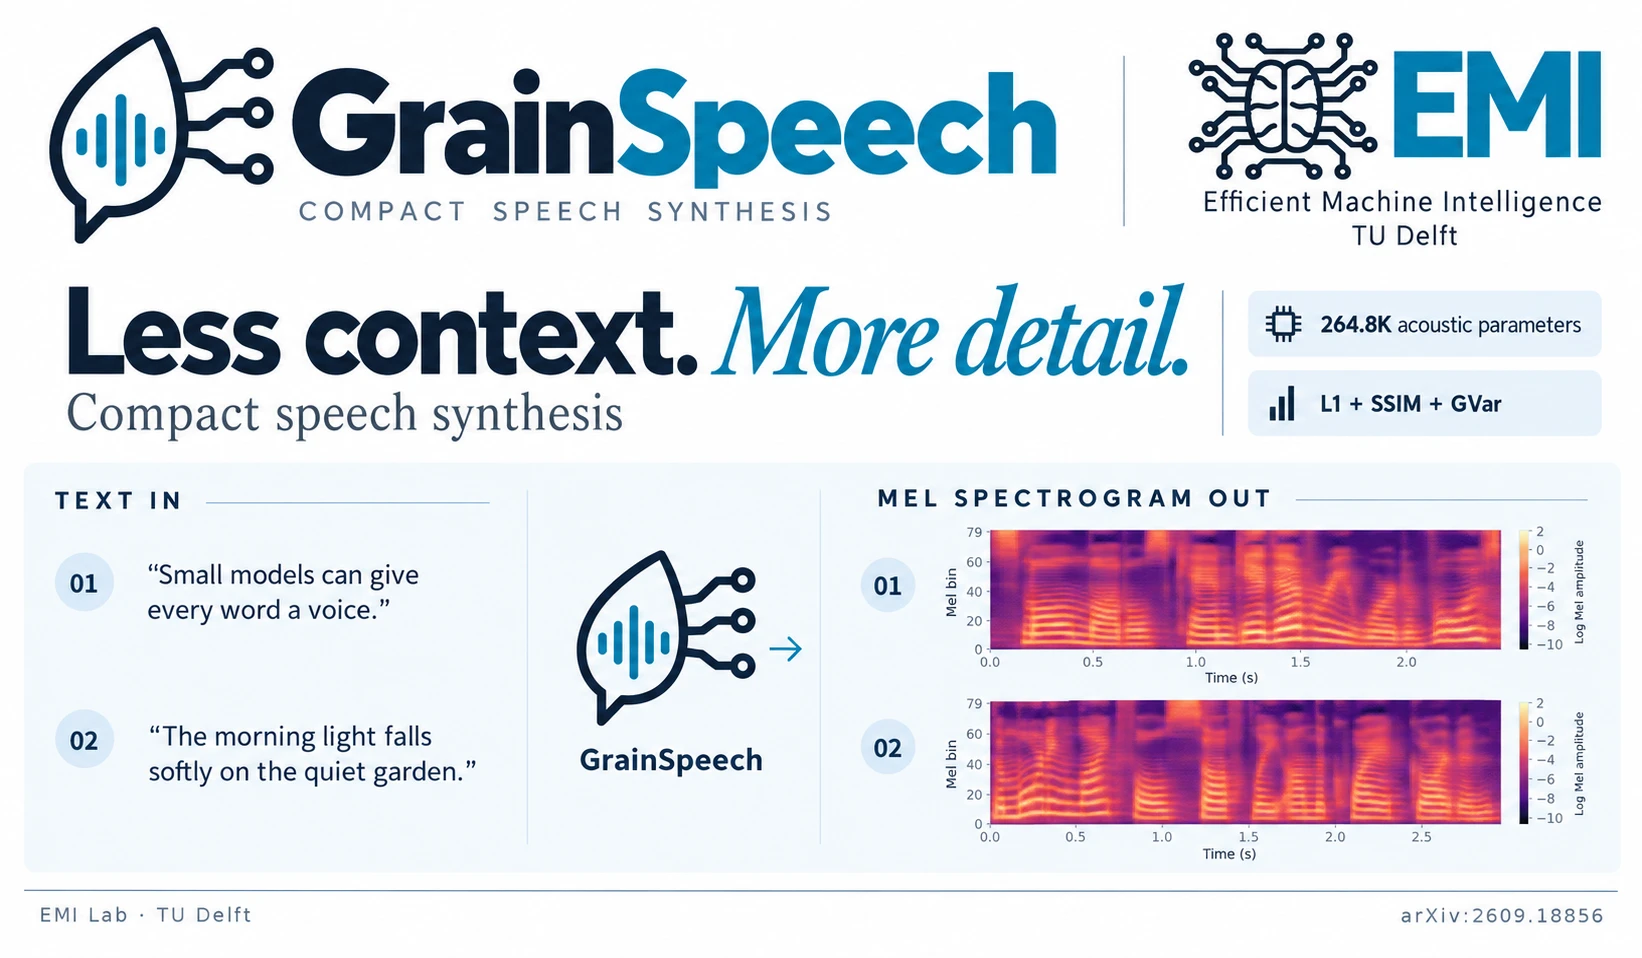
Our new arXiv preprint, GrainSpeech: Less Context, More Detail for Compact Speech Synthesis, by Zitao Liang and Chang Gao, is now available.
GrainSpeech combines a fixed-receptive-field convolutional encoder with Mel-spectrogram supervision designed to preserve fine acoustic detail. The acoustic model has just 264.8K parameters, supporting our work on efficient speech synthesis for embedded systems.
Explore the GrainSpeech repository for the code, pretrained checkpoint, example spectrograms, audio demos and instructions.